
Concepts
Recording
Streams flow continuously. Recording appends samples to Zarr. Labels form a separate timestamped event track. They are never interleaved with signal samples, so signals and labels can be read independently. This keeps signal arrays cheap to slice and labels cheap to scan.
Mental model
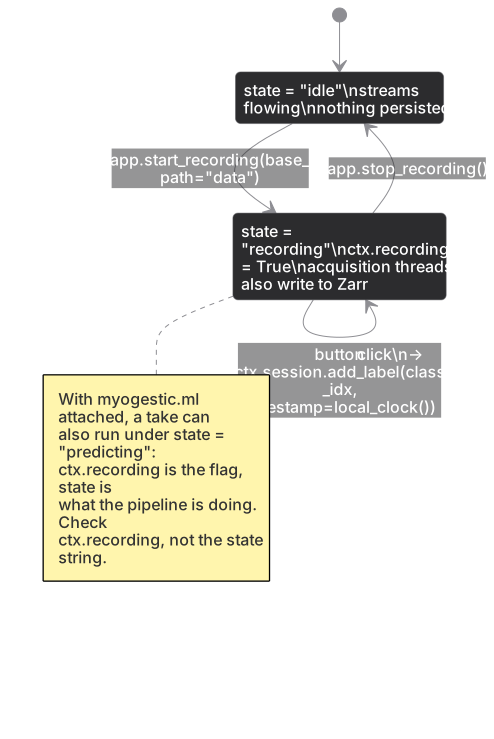
Acquisition threads append each chunk while their stream has an attached session. Stop detaches the streams, freezes event buffers, then finalizes metadata and the archive on a daemon thread.
ctx.recording indicates whether a take is open, independently of ctx.state. From idle, Record moves the state to recording; while a Pipeline is predicting, Record leaves the state alone and sets the flag. RECORDABLE_STATES in myogestic.core lists the states a take may start from. Core registers idle, myogestic.ml registers predicting. ctx.session stays set after a stop so the signal viewer can keep drawing the last take’s label markers; do not use it as the flag.
On-disk layout
Everything for one participant lives in one folder under data/, split by what it is:
data/├── P-014/│ ├── recordings/ # takes started from idle: training data│ │ └── P-014_20260506-1846_R.mg.zip│ ├── predictions/ # takes started while a model was predicting│ │ └── P-014_20260506-1852_follow-F.mg.zip│ └── models/ # Pipeline.autosave_dir output│ └── P-014_20260506-1850_spar-mlp.joblib├── recordings/ # takes recorded with no participant set└── predictions/app.start_recording() picks recordings/ or predictions/ from ctx.state when the take
starts, so a prediction run never lands among the training takes.
participant_dir(root, participant, kind) returns any
of these folders. How each file is named, gesture codes included, is in
File names.
During recording, one folder per take:
data/P-014/recordings/└── P-014_20260506-1846/ ├── meta.json # class_names, created, streams, extras (checkpointed; finalised on stop) ├── labels.json # timestamps + class indices (checkpointed with metadata) ├── emg.zarr/ # (n_samples, n_channels) sample-major ├── emg_timestamps.zarr/ # (n_samples,) float64 LSL clock ├── imu.zarr/ # if a second stream was recorded └── imu_timestamps.zarr/After stop_recording, the folder packs to a single archive:
data/P-014/recordings/└── P-014_20260506-1846_R.mg.zip # archive - contains the same internal layoutThe source folder is removed after a successful pack; if packing fails, it is kept. Saved folders and archives are both loadable via open_session_store(path). Readers need no format-specific branch.
Notifications
App draws corner toasts automatically after your UI. Call ctx.notify(title, detail="", kind="info") from the UI or a worker thread; each toast also becomes a timestamped
ctx.log line.
from myogestic import Context
ctx = Context()ctx.notify("Recording saved", "a.mg.zip", "success")assert ctx.logs[-1].endswith("Recording saved — a.mg.zip")
success and info last 6 seconds, warning lasts 10 seconds, and danger stays until
dismissed. Hovering the overlay pauses expiry. At most the newest three toasts appear;
older events remain in the log. Click a toast’s × to dismiss it. An unknown kind
raises ValueError.
Stopping a recording reports Recording saved with the archive’s filename after packing succeeds. If packing fails, Recording not packed shows the error and confirms that the session folder was kept.
Labels
LabelEvent stores a timestamp and class index.
@dataclassclass LabelEvent: timestamp: float # pylsl.local_clock() at the button click class_index: int # -1 = unlabeled (terminator)The label track is a list of these events, persisted to labels.json on stop. Each consecutive pair (events[i], events[i+1]) defines one trial. Every sample in between is labelled class_index. An optional -1 event marks an unlabeled boundary. Without a closing event, the last trial extends to the end of the recorded samples.
RecordingControls writes labels when the user clicks a button:
rec_controls = RecordingControls( ["Rest", "Fist", "Open"], on_record=app.start_recording, on_stop=app.stop_recording, on_gesture=lambda idx: ctrl_outlet.push_sample([float(idx)]),)rec_controls.ui(ctx)Use on_gesture to change a synthetic generator’s pattern through a control LSL stream, command a robot or log the gesture. RecordingControls adds the label before calling your callback.
Event streams
A sampled stream has a clock; an event stream has one row per thing that happened. Session.append_event(name, values, timestamp, channel_names=..., fs=...) declares such a stream on first use and appends one float32 row to it. On disk it is the same <name>.zarr / <name>_timestamps.zarr pair as any stream, so open_session_store, ReplaySource and the window iterators can read it. meta.json lists these names under event_streams, and their nominal fs is the producer’s tick rate, used by ReplaySource for pacing. Timestamps are authoritative for event times; nominal fs is only for replay pacing.
Rows are buffered in memory and written 1024 at a time or once a second, whichever comes first, because a single-row zarr append rewrites the partial chunk, taking about 1.5 ms each on zarr 3.2. Session.freeze() flushes every buffer and closes the session to new rows and new streams; App.stop_recording calls it before finalization metadata and the archive are written.
Rows are float32 by default; clock values such as LSL timestamps from local_clock() lose milliseconds at float32 after a day of uptime. Pass dtype=np.float64, as the pipeline does for pipeline.tick, or record an offset.
With a take open, two producers write event streams for you:
| Stream | Written by | One row per | Timestamp |
|---|---|---|---|
features or features.<key> |
Pipeline, what @pipeline.extract returned |
predict tick | newest sample the tick consumed |
prediction.<key> |
Pipeline, what @pipeline.predict returned |
predict tick | same |
pipeline.tick |
Pipeline, the LSL local_clock() at the decision |
predict tick | same; tick − timestamp is the latency |
controls |
ControlBus, the continuous frame it delivered, DOF names as channels |
push |
delivery clock |
controls.<name> |
A second bus with record_as="controls.<name>"; its map is saved in meta.control_spaces |
push |
delivery clock |
A dict becomes one stream per key. A value is recorded when it is a bool, a number, or a 1-D array; text, None, nested dicts and anything 2-D or wider are skipped, logged once, and listed under extras.pipeline.skipped in meta.json. A raw window returned by extract is the recorded stream already; a CNN history is rebuilt from consecutive frames.
For a take that recorded pipeline ticks, extras.pipeline identifies it as a Drive run. Takes shows a Drive tag and leaves it unticked for training; the operator can still tick it. Continue → Train selects ordinary takes and skips Drive runs.
On stop, App.finalize_hooks run on the finalize thread before meta.json is updated with finished: true. The pipeline’s hook saves the running model as model.joblib beside the arrays when pipeline.save_model is set. It writes extras.pipeline with the model type, its report if it has one, the event streams, and the skip list.
Reading recordings
from myogestic.session import open_session_store
sess = open_session_store("data/P-014/recordings/P-014_20260506-1846_R.mg.zip")
# Continuous datadata, ts = sess.get_continuous("emg")# data.shape == (n_samples, n_channels)  - sample-major as recorded
# Per-trial slices (labelled segments)trials = sess.get_trials("emg", pre_s=0, post_s=0)# list[Recording] - each has .data, .timestamps, .class_index, .class_name# Pass class_names=sess.class_names to get names rather than numeric strings.
# Stream metadatainfo = sess.stream_info("emg")  # StreamInfo(n_channels, fs, dtype, channel_names)
For training pipelines, two iterators do the slicing for you:
Classification - iter_labeled_windows
from myogestic.session import iter_labeled_windows
for window, ts, class_idx in iter_labeled_windows(    data.paths,    stream_name="emg",    window_ms=200,    hop_ms=100,    classes={0, 1},):    feat = rms(window)  # window is (n_channels, n_samples)    X.append(feat)    y.append(class_idx)
Yields one window per hop_ms step, dropping windows that straddle a label boundary so each window has exactly one class. The three-tuple is (window, ts, class_index). ts is the matching 1-D timestamp array for per-sample alignment.
Regression - iter_aligned_windows
from myogestic.session import iter_aligned_windows
for window, aligned, ts in iter_aligned_windows(    data.paths,    primary_stream_name="emg",    aligned_stream_names=["vhi_control"],    window_ms=200,    hop_ms=50,    n_alignment_samples=1,):    feat = extract(window)    target_pose = aligned["vhi_control"]  # shape (n_channels,)
Yields the primary window plus a target snapshot nearest its midpoint, averaging n_alignment_samples around that target index, per aligned_stream_names entry. Use this for continuous targets such as kinematics, torque or joint angles.
Backends
Zarr is the storage layer. Two compression backends are supported.
- Pure-Python
zarris the default and works everywhere. zarrsprovides faster Rust compression through PyO3. Install it withuv sync --extra zarrs.
On desktop Zarr 3, if zarrs is installed, its codec pipeline is selected on import; if not, recording falls back to plain zarr with no code change.
Common mistakes
See Troubleshooting for symptoms and fixes.
sess.class_names = [...]aftersave_meta. Pass class names tosave_meta(name, class_names=...)to persist them. Setting the attribute after saving does not persist them.RecordingControlshandles this throughapp.start_recording.- Treating the label track as a stream. Labels are events. To iterate “rest periods” by time, slice with the labels and the timestamp arrays manually, or use
iter_labeled_windows. - Too little data.
iter_labeled_windowsuses every nonnegative labeled segment long enough for a window; it does not skip the first trial. Record several sustained trials per class. Do not rely on one short segment.